tf.keras.callbacks.EarlyStopping is used to terminate a training if a monitored quantity satisfies some criterion. For example, in the following code snippet, the training will stop before reaching the target epoch (10000 in this case) if the training loss has not improved for 3 epochs in a roll:
stop = tf.keras.callbacks.EarlyStopping( monitor="loss", min_delta=1e-3, patience=3)model.fit(..., epochs=10000, callbacks=[stop])min_delta=1e-3 represents how large a change must be to count as an improvement.
In the example above, some people, and I admit I used to be one of them, may expect that when the training is stopped by EarlyStopping, the last 3 or 4 epochs should have similar values because the loss is no longer improving. In other words, people may think the training stopped because the loss converged to some value, and continuing the training would not reduce the loss much.
That expectation corresponds to a situation where the last 4 losses are, for example, 0.01, 0.0105, 0.0092, and 0.0099. The last 3 losses do not differ from 0.01 by more than 1e-3. But that expectation is WRONG.
Before we look into the source code to understand what EarlyStopping does, let’s read the API documentation again:
Stop training when a monitored quantity has stopped improving.
It only says “a monitored quantity has stopped improving”. It does not say “a monitored quantity has converged”.
So it is also possible that the training is stopped because the loss blew up for 3 epochs in a row. For example, if the losses of the last 4 epochs are 0.01, 1.2, 2.05, and 3.0, EarlyStopping also stops the training.
Because training may stop due to blowing up, we are not guaranteed to get an optimized model at the last epoch. Even worse, we may end up with a model that has a very large loss. That is why EarlyStopping has an optional argument called restore_best_weights. It helps recover the model weights that gave us the best prediction during training.
Now let’s read the source code of EarlyStopping. The code of the current version is here:
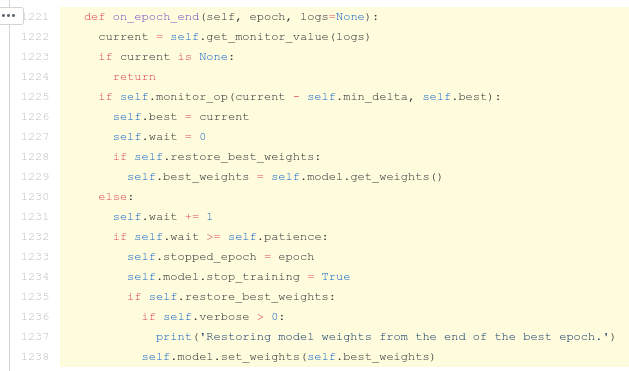
Code of EarlyStopping.on_epoch_end (snippet from TensorFlow’s GitHub repo)
self.monitor_op is < (less than) for quantities like loss or root mean squared error, and it is > (greater than) for quantities like accuracy.
We can see from line 1225 that if the current loss + min_delta (1e-3 in our case) is less than the best loss in the training history, it is treated as an improvement and updates the best-loss record. Any situation in which the current loss + min_delta is not less than the best record (line 1230) is treated as “not improving” and increases the count of consecutive epochs without improvement.
That “any situation” obviously includes the case where the current loss is greater than the best record. So EarlyStopping will stop training if the monitored quantity blows up.
Anyway, coming from the world of traditional numerical methods, I expected that an iterative solver would stop early only when the residual, i.e. the loss, converged to some value and no longer changed significantly. If I want to terminate a solver early because it is blowing up, I would usually use another mechanism that detects whether the solver diverges. I rarely combine convergence detection and divergence detection into a single mechanism.
And when a solver stops because of divergence, I do not usually say that it “stops” in the same sense. I tend to use the word “stop” only when describing a solver that finishes successfully. And obviously, divergence is not a successful solve. That is why I did not really expect tf.keras.callbacks.EarlyStopping to terminate a training process when the loss blows up.